Where HGX B300 pays off
Large-scale LLM workloads
Train, fine-tune, and serve frontier language models on a platform built for memory-intensive workloads.
HGX B300 carries significantly more memory per GPU than its predecessor, enabling larger models, longer context windows, and higher concurrency at production scale.
Multimodal AI
Build and deploy AI systems that combine text, images, audio, or video.
HGX B300 architecture efficiently balances compute and memory bandwidth, making it a practical platform for developing and running next-generation multimodal models.
AI reasoning and agentic AI
Develop and scale reasoning models and agentic systems that generate significantly more tokens per request.
HGX B300 memory capacity and compute profile sustain the throughput these workloads require, without the constraints that limit smaller-memory platforms.
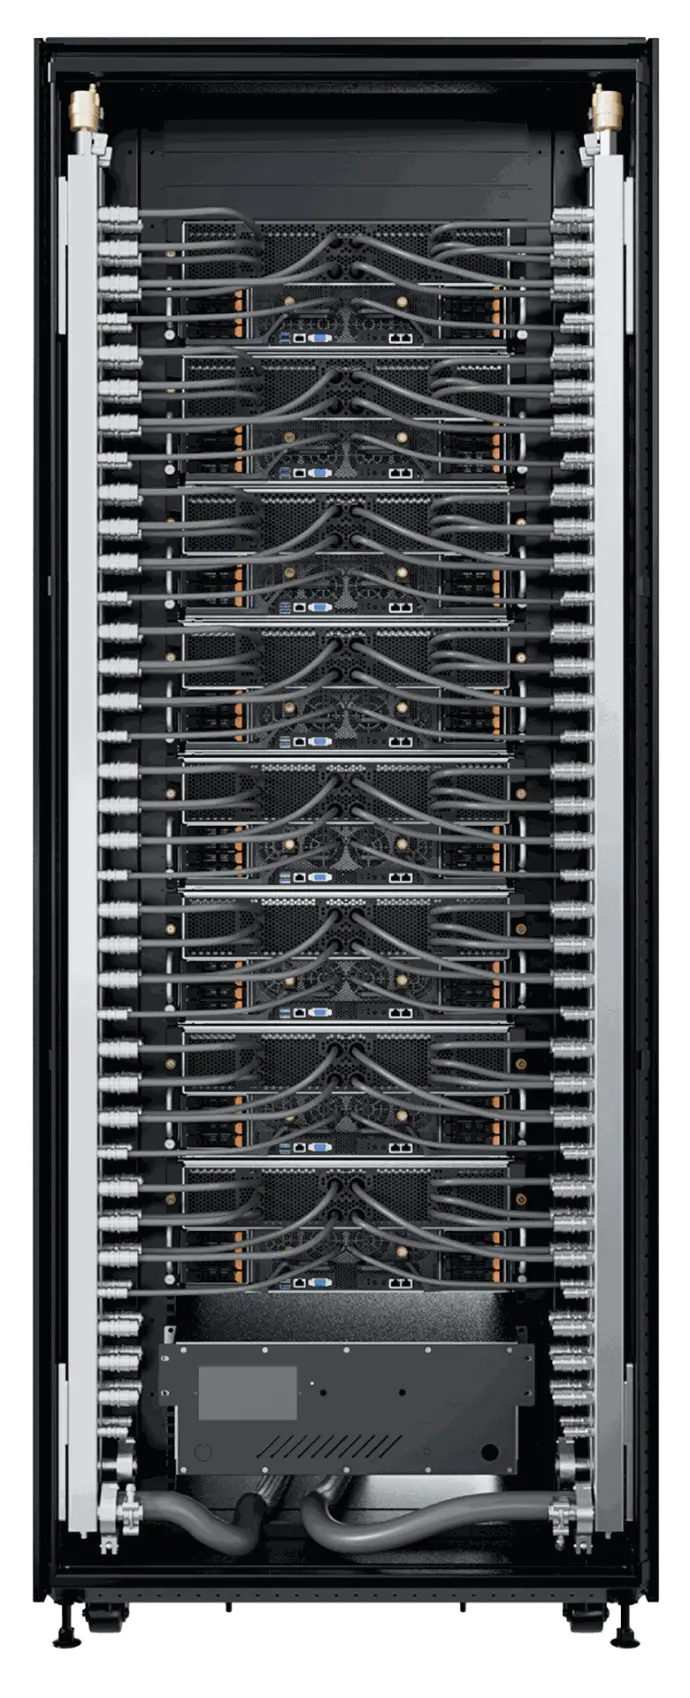
Rack solution
fully configured for AI at Scale
Redefine Your AI Infrastructure at Scale
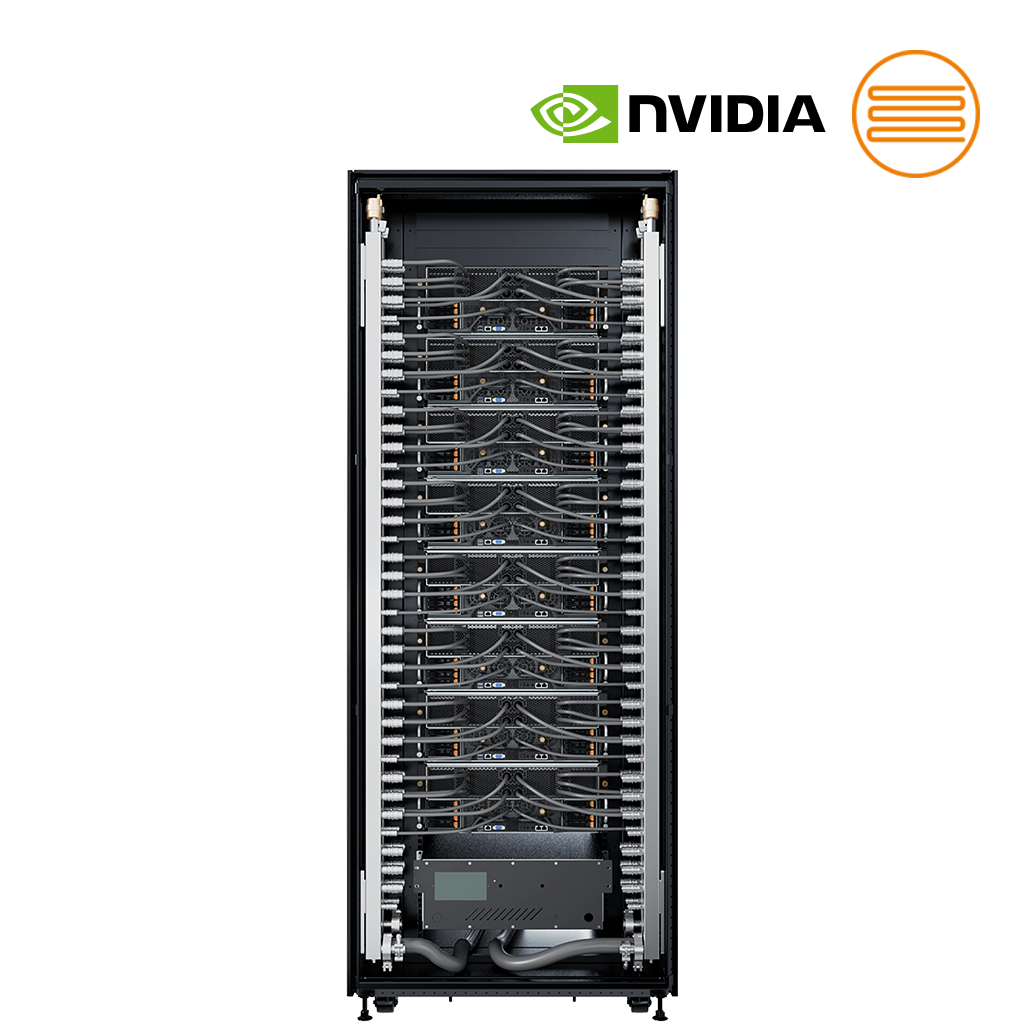
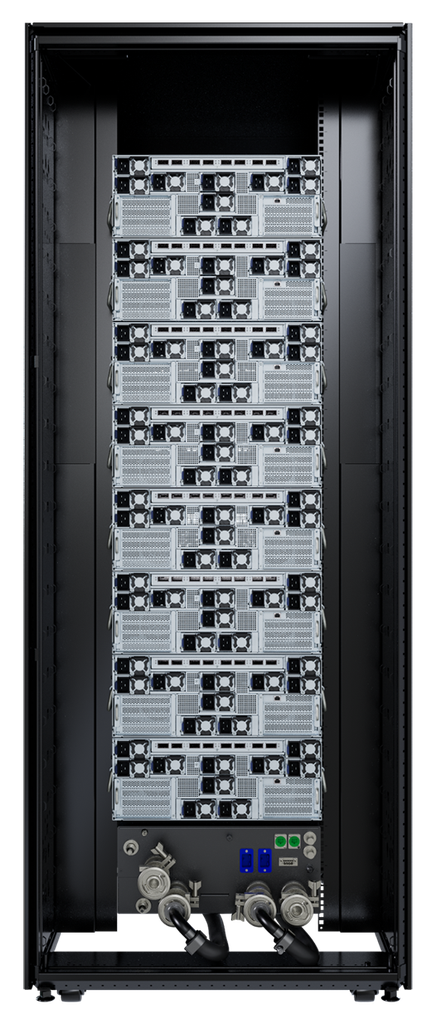
This rack solution, built on the NVIDIA HGX™ B300 platform, is a turnkey AI Infrastructure engineered for the most demanding workloads. From large language model training to agentic AI and multimodale AI inference, this solution delivers uncompromising performance, thermal efficiency, and operational simplicity, all within a single, fully integrated rack.
Scalable from Day One
This ecosystem is designed to grow with your business. If you are deploying a single rack or scaling to a multi-rack AI supercomputer with hundreds of GPUs, we provide a proven, end-to-end solution backed by deep partnerships with NVIDIA.
As an NVIDIA-certified partner, we hold every component, configuration, and deployment to NVIDIA's validation standards for AI infrastructure. The result: proven compatibility, optimized performance, and reliability you can build mission-critical workloads on.
Turnkey deployment | NVIDIA-certified
Multi-rack scalability | Integrated liquid cooling
AI Training & Inference Performance with B300
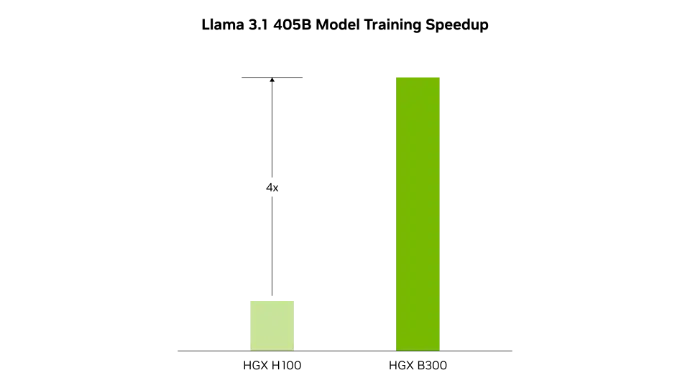
AI Training
 Courtesy of NVIDIA.
The second-generation Transformer Engine, featuring 8-bit floating point (FP8) and new precisions, enables a remarkable 4x faster training for large language models like Llama 3.1 405B.
AI Reasoning Inference
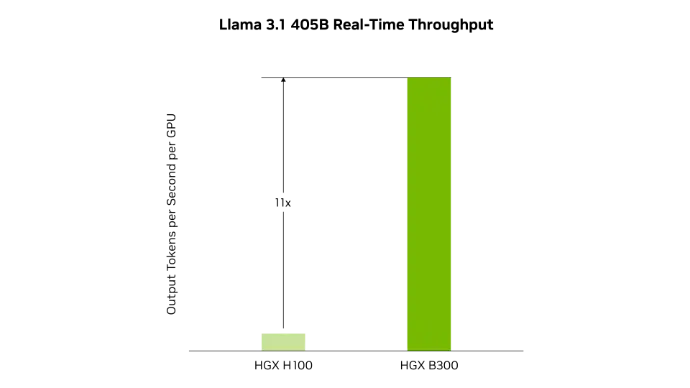
Courtesy of NVIDIA.
HGX B300 achieves up to 11x higher inference performance over the previous H100 generation for models such as Llama 3.1 405B.
Direct Liquid Cooling
Increase your data center density and achieve a PUE < 1.1 with the efficiency of our DLC solutions.
Coolant Distribution Unit
The in-rack liquid-to-liquid CDU delivers 200 kW of cooling capacity at a 4°C approach temperature, bringing direct-to-chip liquid cooling to high-density racks without requiring facility-level infrastructure changes.
The unit runs on standard single-phase AC 220–240 V / 50–60 Hz power, simplifying deployment in existing data center environments. Built for continuous operation, it features 1+1 redundant power supplies and pumps, so a single component failure never interrupts cooling to the rack.
Deploying a multi-rack AI supercomputer with hundreds or thousands CPUs? We can propose more optimized configurations, including in-row CDUs supporting up to 1350 kW.
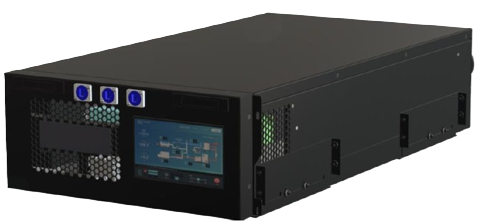
In-Rack CDU
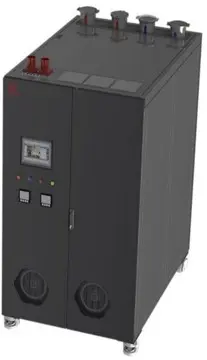
In-Row CDU (for large scale deployment)