Built for the workloads that define next-gen AI
Large-scale LLM workloads
Train, fine-tune and serve frontier models without memory as the bottleneck.
With HBM4 on every GPU and a big jump in memory bandwidth, HGX Rubin NVL8 fits larger models, longer context windows and more concurrent users on each node. You serve more at production scale with fewer compromises.
Multimodal AI
Text, images, audio and video, all on one platform.
Multimodal pipelines need both raw compute and fast data movement. HGX Rubin NVL8 balances the two, so you can develop and run next-generation multimodal models without one side holding the other back.
AI reasoning and agentic AI
More tokens per request, delivered without slowing down.
Reasoning models and AI agents generate far more tokens per task than standard inference. HGX Rubin NVL8 combines high memory capacity, bandwidth and NVLink connectivity to sustain that throughput and keep latency low where smaller-memory platforms fall short.
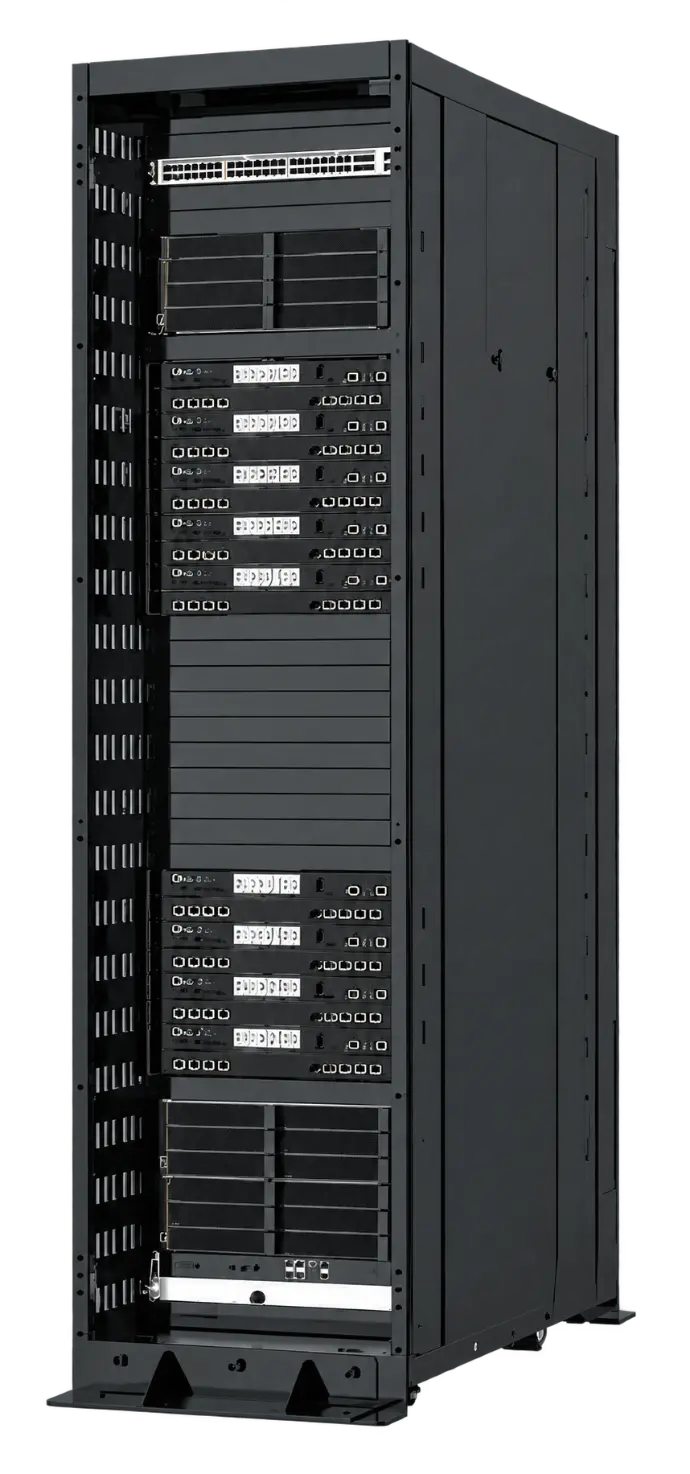
Turnkey deployment / NVIDIA-certified / Redundant Power Distribution / Multi-rack scalability
Rack solution
fully configured for AI at Scale
Scaling AI Factories for Enterprise
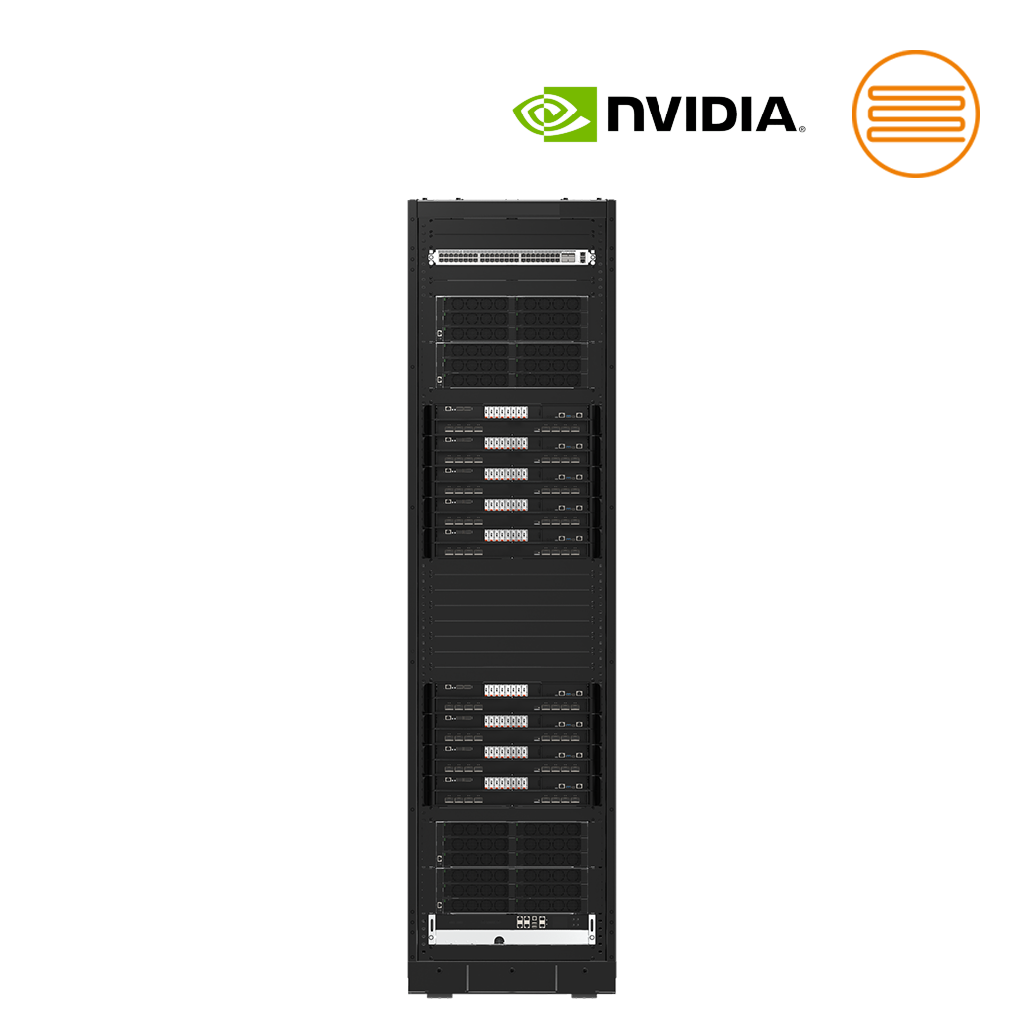
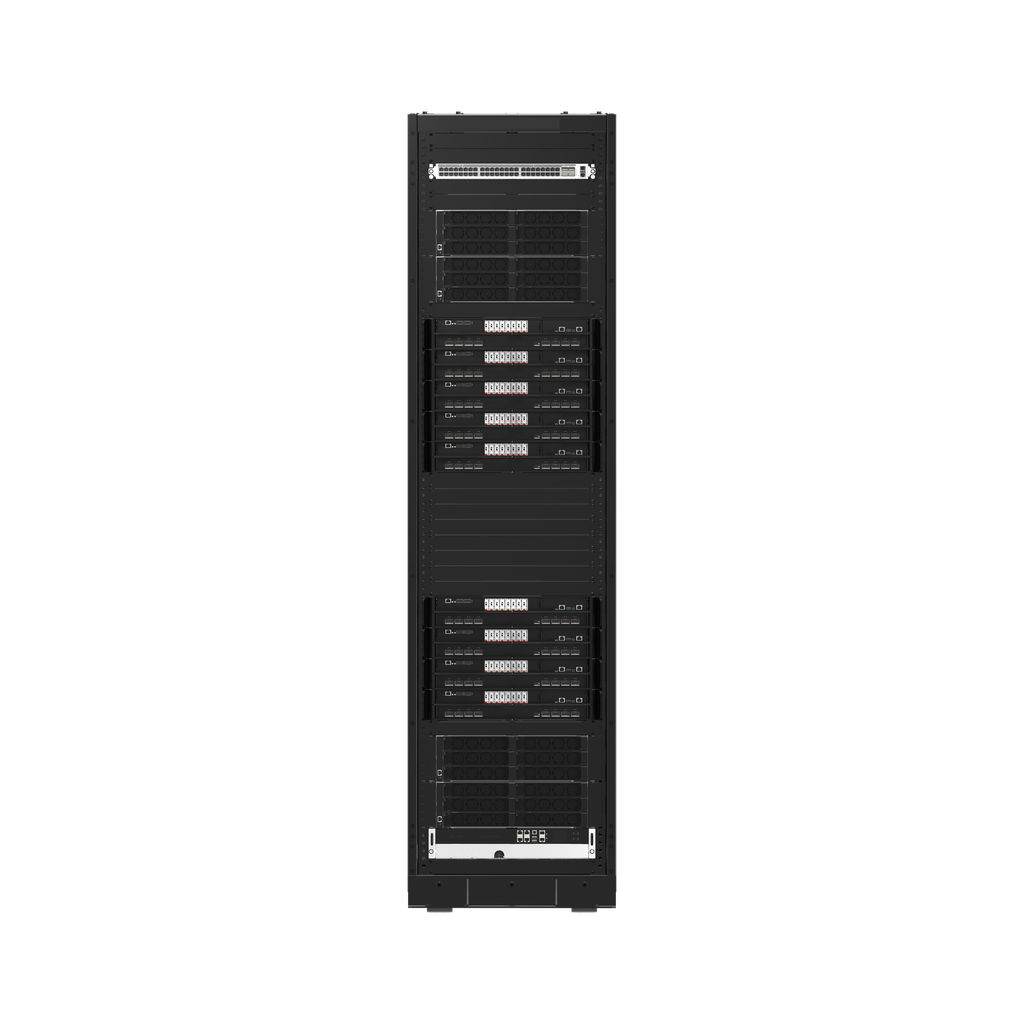
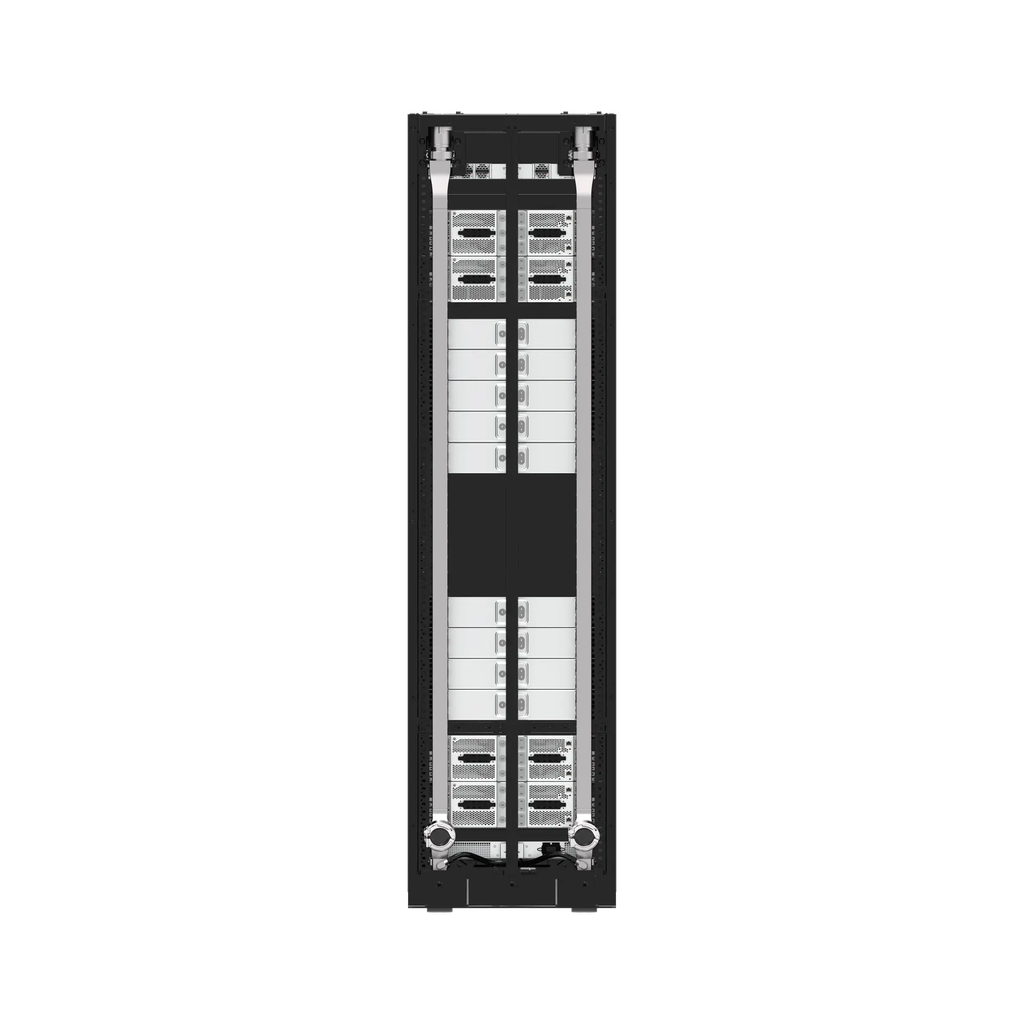
This rack solution, built on the NVIDIA HGX™ Rubin NVL8 platform, is a turnkey AI Infrastructure engineered for the most demanding workloads. From large language model training to agentic AI and multimodale AI inference, this solution delivers uncompromising performance, thermal efficiency, and operational simplicity, all within a single, fully integrated rack.
Scalable from Day One
This ecosystem is designed to grow with your business. If you are deploying a single rack or scaling to a multi-rack AI supercomputer with hundreds of GPUs, we provide a proven, end-to-end solution backed by deep partnerships with NVIDIA.
As an NVIDIA-certified partner, we hold every component, configuration, and deployment to NVIDIA's validation standards for AI infrastructure. The result: proven compatibility, optimized performance, and reliability you can build mission-critical workloads on.
AI Training & Inference Performance with Rubin
AI Training
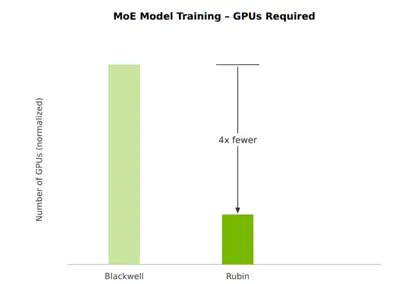
Source: NVIDIA Rubin platform announcement (CES 2026).
NVLink 6, 288 GB of HBM4 per GPU and the third-generation Transformer Engine (NVFP4) let Rubin train large MoE models with 4x fewer GPUs than Blackwell.
AI Reasoning Inference
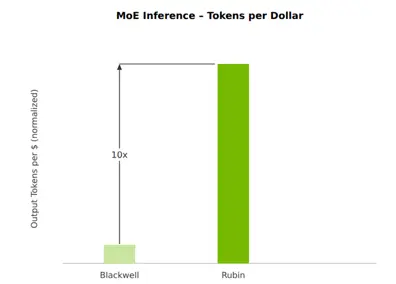
Source: NVIDIA Rubin platform announcement (CES 2026).
NVIDIA Rubin delivers up to 10x lower cost per token than the Blackwell generation for mixture-of-experts reasoning models.
Direct Liquid Cooling
Increase your data center density and achieve a PUE < 1.1 with the efficiency of our DLC solutions.
Coolant Distribution Unit
HGX Rubin systems are fully liquid-cooled platforms, designed from the ground up for direct-to-chip cooling at extreme rack densities. At these power levels, cooling moves from the rack to the row. Coolant is supplied through in-row liquid-to-liquid CDUs, or directly from the facility water loop, which gives higher capacity, better efficiency and simpler serviceability than in-rack units.
The Rubin generation is built for warm-water cooling, with supply temperatures up to 45°C. That cuts or removes the need for chillers, lowering both energy use and total cost of ownership. In-row CDUs with N+1 redundant pumps and power supplies keep cooling running for every rack in the row, even if a single component fails.
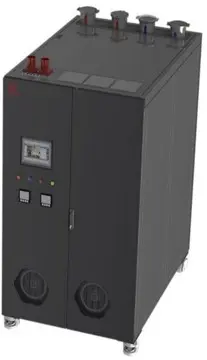
In-Row CDU
Whether you're deploying a few HGX Rubin nodes or a multi-rack AI supercomputer with thousands of GPUs, our team sizes the complete cooling architecture for you. That covers in-row CDUs supporting up to 1,350 kW, secondary fluid networks and heat-rejection integration with your existing facility.